Humyn Labs, a physical AI research lab focused on accelerating the deployment-readiness of robots in the real world, has launched the second edition of BRIDGE, an independent benchmark report examining the gap between human speech and AI voice models.
The benchmark evaluated 23 voice AI models across 23 languages using real-world noisy conversations, including models such as Sarvam v3, Gemini 3 Pro and ElevenLabs. It assesses voice models across seven core metrics, including overlapping speech, conversational density and code-switching.
Real-world speech challenges
The latest edition covers Indic languages along with Latin American Spanish, Brazilian Portuguese and Vietnamese. It is based on more than 200 hours of human-verified real-world audio collected across two to three districts per language.
The report found that overlapping speech increased the average error rate from 41.2% to 45.2%. Dialect differences also had a significant impact. Bengali recorded a 42.4% error rate in its standard form, compared with 51% for a regional dialect outside Kolkata.
A similar pattern emerged in Spanish, with Argentinian Spanish recording a 7.85% word error rate against 16.04% for Venezuelan Spanish.
Model performance varies sharply
Model selection also emerged as a major factor in transcription accuracy. ElevenLabs, the top performer across five non-Indic languages tested, recorded an average error rate of 5.8%, compared with 24.6% for GPT-4o-mini-transcribe on the same audio.
The report also found that long pauses can affect accuracy. Brazilian Portuguese calls with gaps exceeding 150 seconds recorded an 18.8% error rate, compared with 12.4% for shorter pauses of around 35 seconds.
BRIDGE also distinguishes genuine transcription errors from script mismatches. In Bengali, Soniox and Sarvam v3 recorded raw error rates of around 20% to 21%, with roughly half attributed to English loanwords being written in a different script rather than being misheard.
Different models fail differently
The benchmark found that 19 of the 23 models typically substitute an incorrect word when they mishear speech. Other models, including OpenAI’s transcription models, Speechmatics and Gnani Vachana, showed a greater tendency to omit words.
Gemini Flash, meanwhile, was found to introduce words that were not spoken, with fabricated content equivalent to 9.3% of the reference transcript’s length.
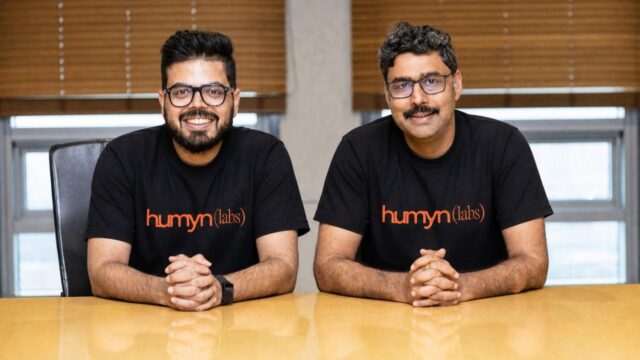
Humyn Labs Co-Founder Manish Agarwal said, “Voice is a critical interface for Physical AI, and therefore voice accuracy becomes a business imperative, not just a technical metric.”
Humyn Labs Co-Founder Ishank Gupta said, “Physical AI cannot learn the real world through vision alone. Sound carries information about people, actions, distance, environment and intent and for a robot operating alongside humans, being able to interpret that signal reliably is fundamental.”
Humyn Labs is building data-enrichment pipelines across voice, vision, motion and touch to help machines interpret real-world environments and accelerate the deployment of robots.